Same-day Sol and Opus — Opus at AA 58 is not your default
Build logBy Daniel Netzeragentshitlagents-in-live-opsagentic-software-factory
Opus at Artificial Analysis 58 is not your org default. Same calendar day, Anthropic shipped Claude Opus 5.5 and OpenAI expanded GPT-6 with Sol and Luna — Sol 48, Luna 37 on the same Index family.
Route on effort × $/task × your harness via Vercel AI Gateway A/B — not Tuesday's Index headline. Two vendor tables stay labeled; one integration point if you already gateway.
Abstract
Opus topping Artificial Analysis at 58 does not mean you should default to it.
On 2026-09-22 Anthropic shipped Claude Opus 5.5 and OpenAI expanded GPT-6 with GPT-6 Sol and Luna. Same calendar day. The independent Index print is useful: Opus 58, Sol 48, Luna 37. Sol is roughly flat vs GPT-5.6 on that Index and roughly halved cost/task on AA’s Index run. None of that is your production receipt. Two vendor tables stay labeled. One integration point if you already route through Vercel AI Gateway. Pick on effort × $/task × your harness, not a single headline score.
At a glance
- Thesis: Opus at AA Intelligence Index 58 ≠ org default. Sol 48, Luna 37 on the same board — useful, still not your escalate rate.
- Anthropic: Claude Opus 5.5. Vendor price $4 / $20 per 1M in/out; API
claude-opus-5-5 - OpenAI: GPT-6 Sol and Luna. Sol $2 / $10; Luna $0.10 / $0.50
- Independent: Artificial Analysis Intelligence Index (max effort). Opus 5.5 58, Sol 48, Luna 37. Sol ~flat vs 5.6 Index;
half cost/task on AA Index ($1.06 vs ~$1.99) - Single integration: Vercel AI Gateway.
anthropic/claude-opus-5.5(+ fast),openai/gpt-6-sol,openai/gpt-6-luna - Harness mismatch (say so): Anthropic Terminal-Bench Opus 66.4% vs AA harness 59.6%
- LMArena: still no Opus 5.5 / GPT-6 Sol / Luna listed (desk check as of this pack)
- Operator takeaway: default the cheaper tier that clears your bar; put Opus on the ambiguous tail
Artificial Analysis: one scoreboard
Artificial Analysis ran both drops on the same Intelligence Index family (v4.3.x). That is the only board I treat as an apples-to-apples composite for this pack. Highest cell on the board is not a fleet default.
| Model (max effort, AA) | Intelligence Index | Notes (AA) |
|---|---|---|
| Claude Opus 5.5 | 58 | Highest AA has measured by several points on their Opus 5.5 article; Terminal-Bench 4.0 59.6% in their harness |
| GPT-6 Sol | 48 | Was 47 for GPT-5.6 Sol max; ~half cost/task on AA’s Index run ($1.06 vs $1.99) |
| GPT-6 Luna | 37 | Flat vs GPT-5.6 Luna; cost/task cut further (~$0.07 vs $0.18) |
Sources: AA Opus 5.5 article, AA Opus model page, AA Sol/Luna article.
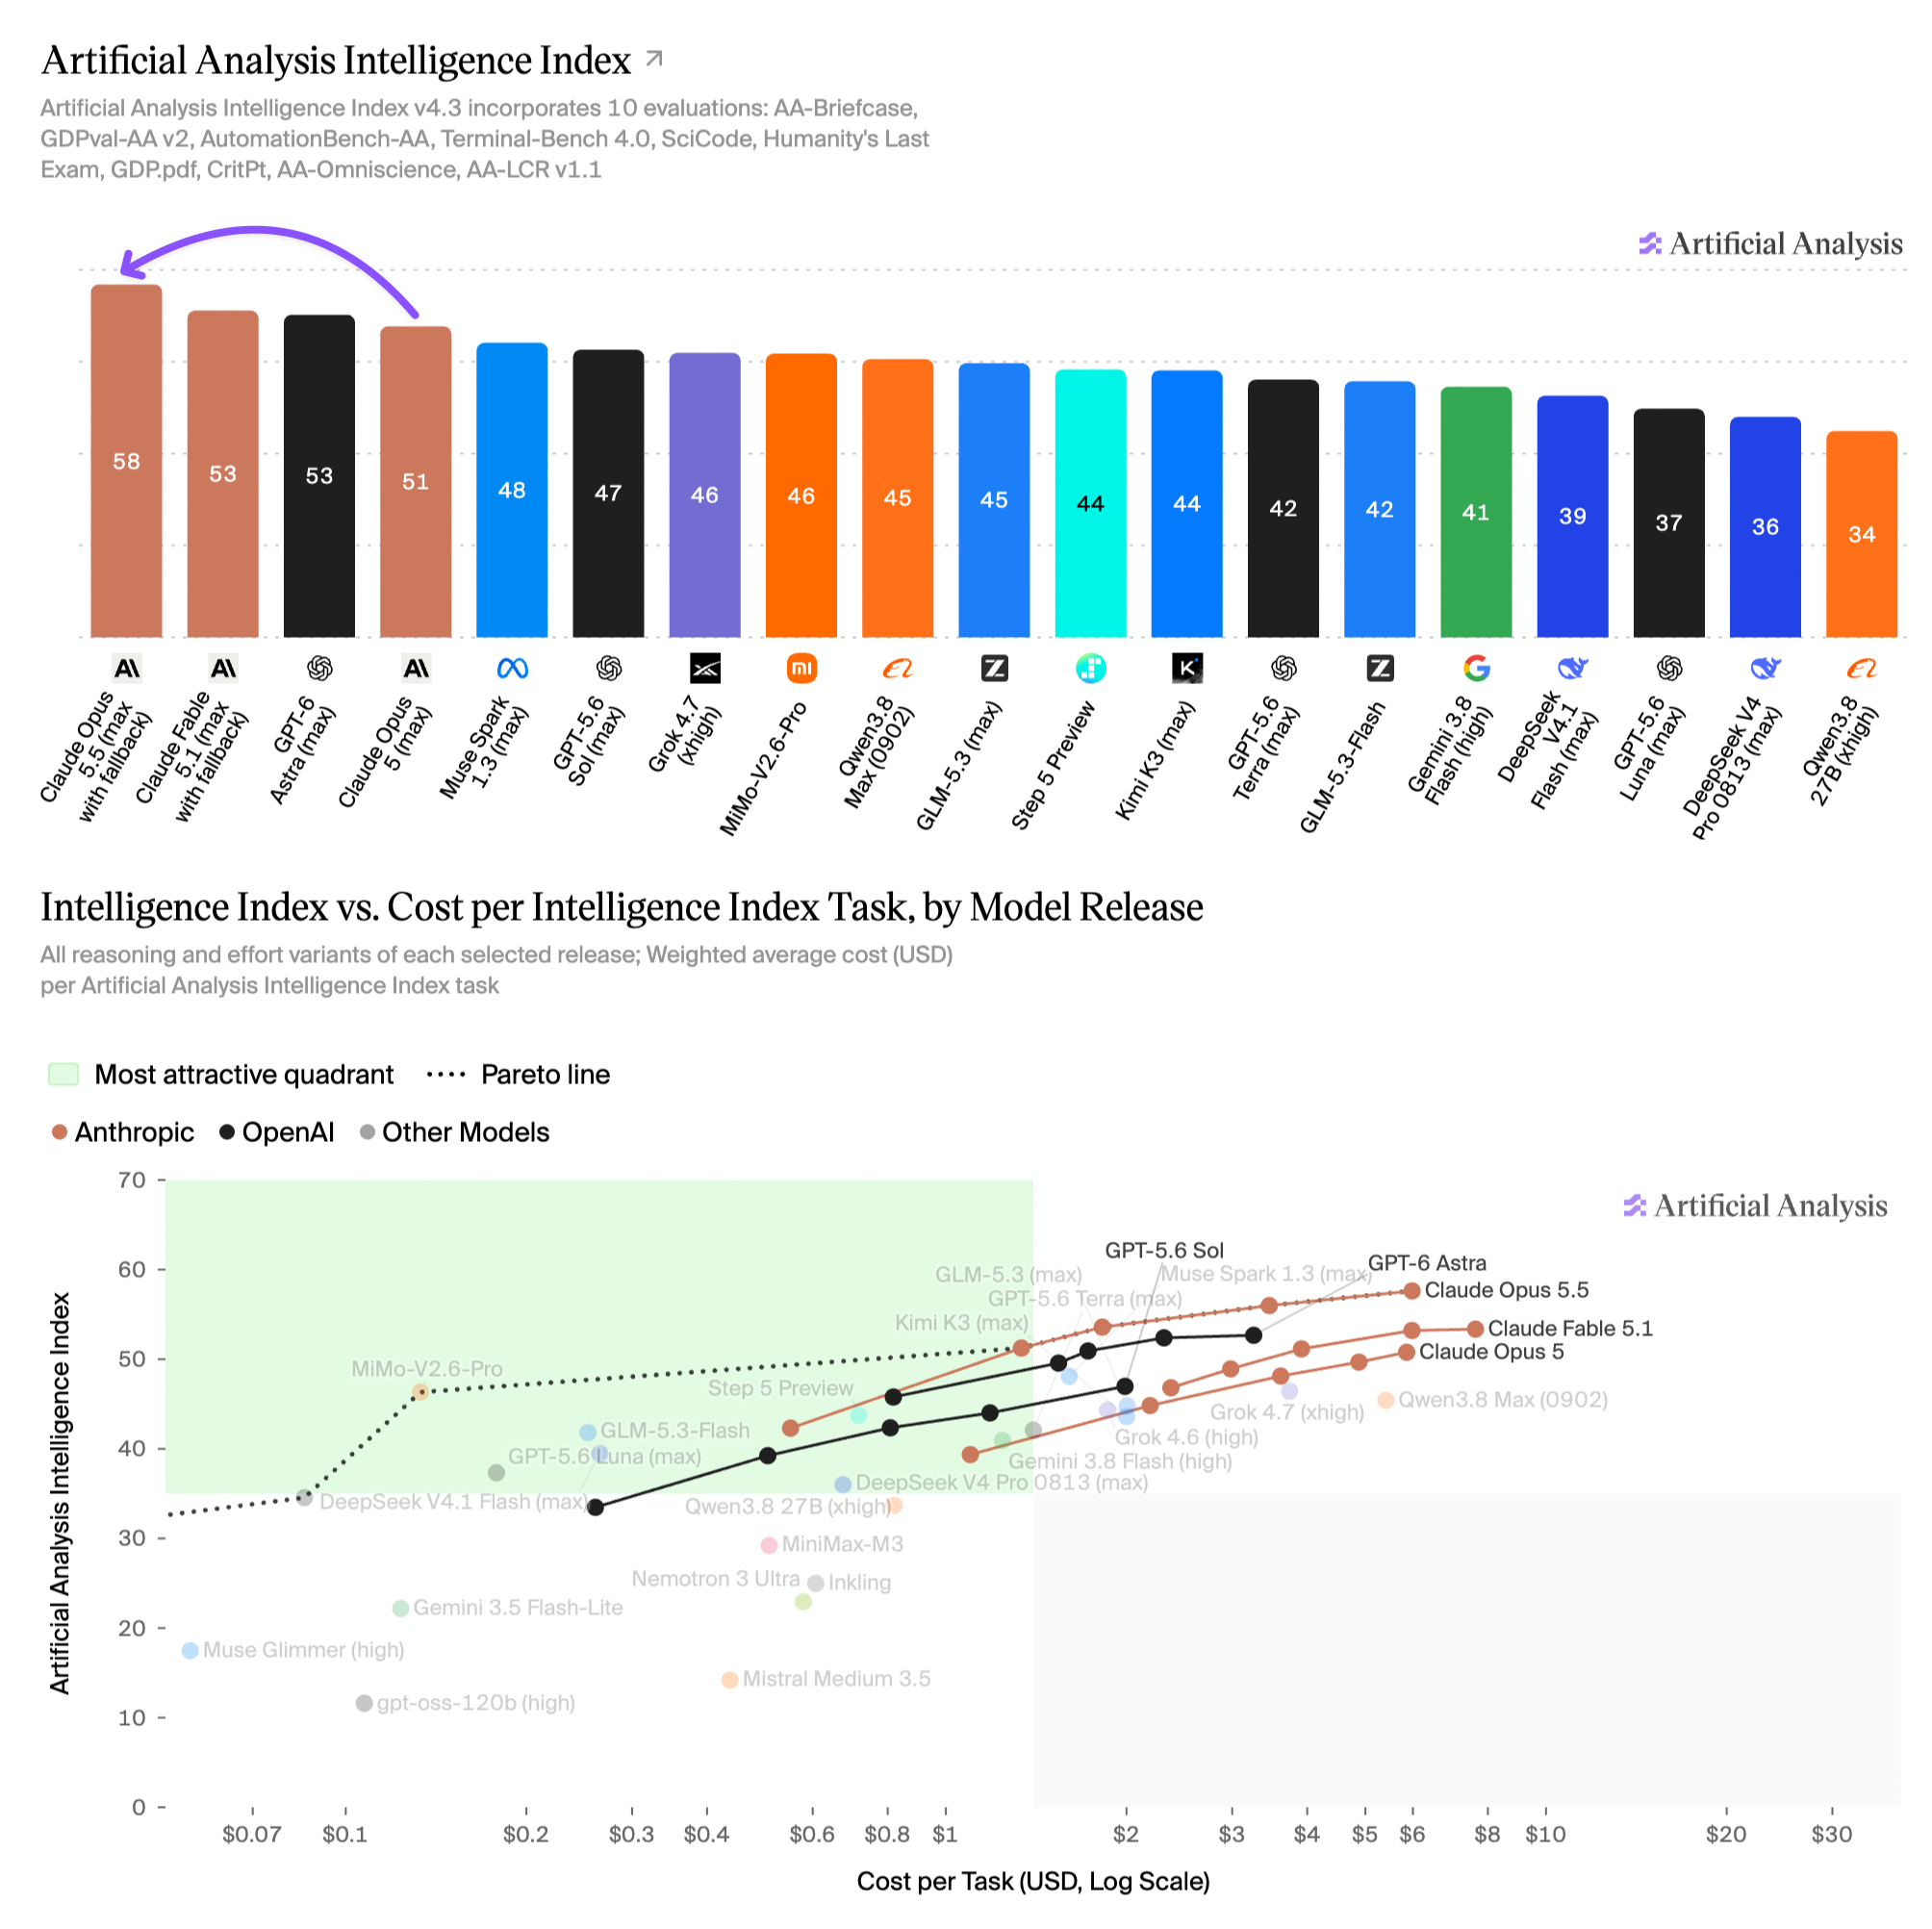
Figure. Artificial Analysis Intelligence Index (v4.3) and Index vs cost per task — from Claude Opus 5.5 takes the top spot… (Sep 22, 2026). Opus max = 58; highest cell is not a fleet default.
AA also flags a mixed picture under Sol/Luna: coding-agent gains for Sol, hallucination cuts, and GDPval-AA regressions (shorter / thinner deliverables on some knowledge-work runs). Cost moved harder than the Index headline.
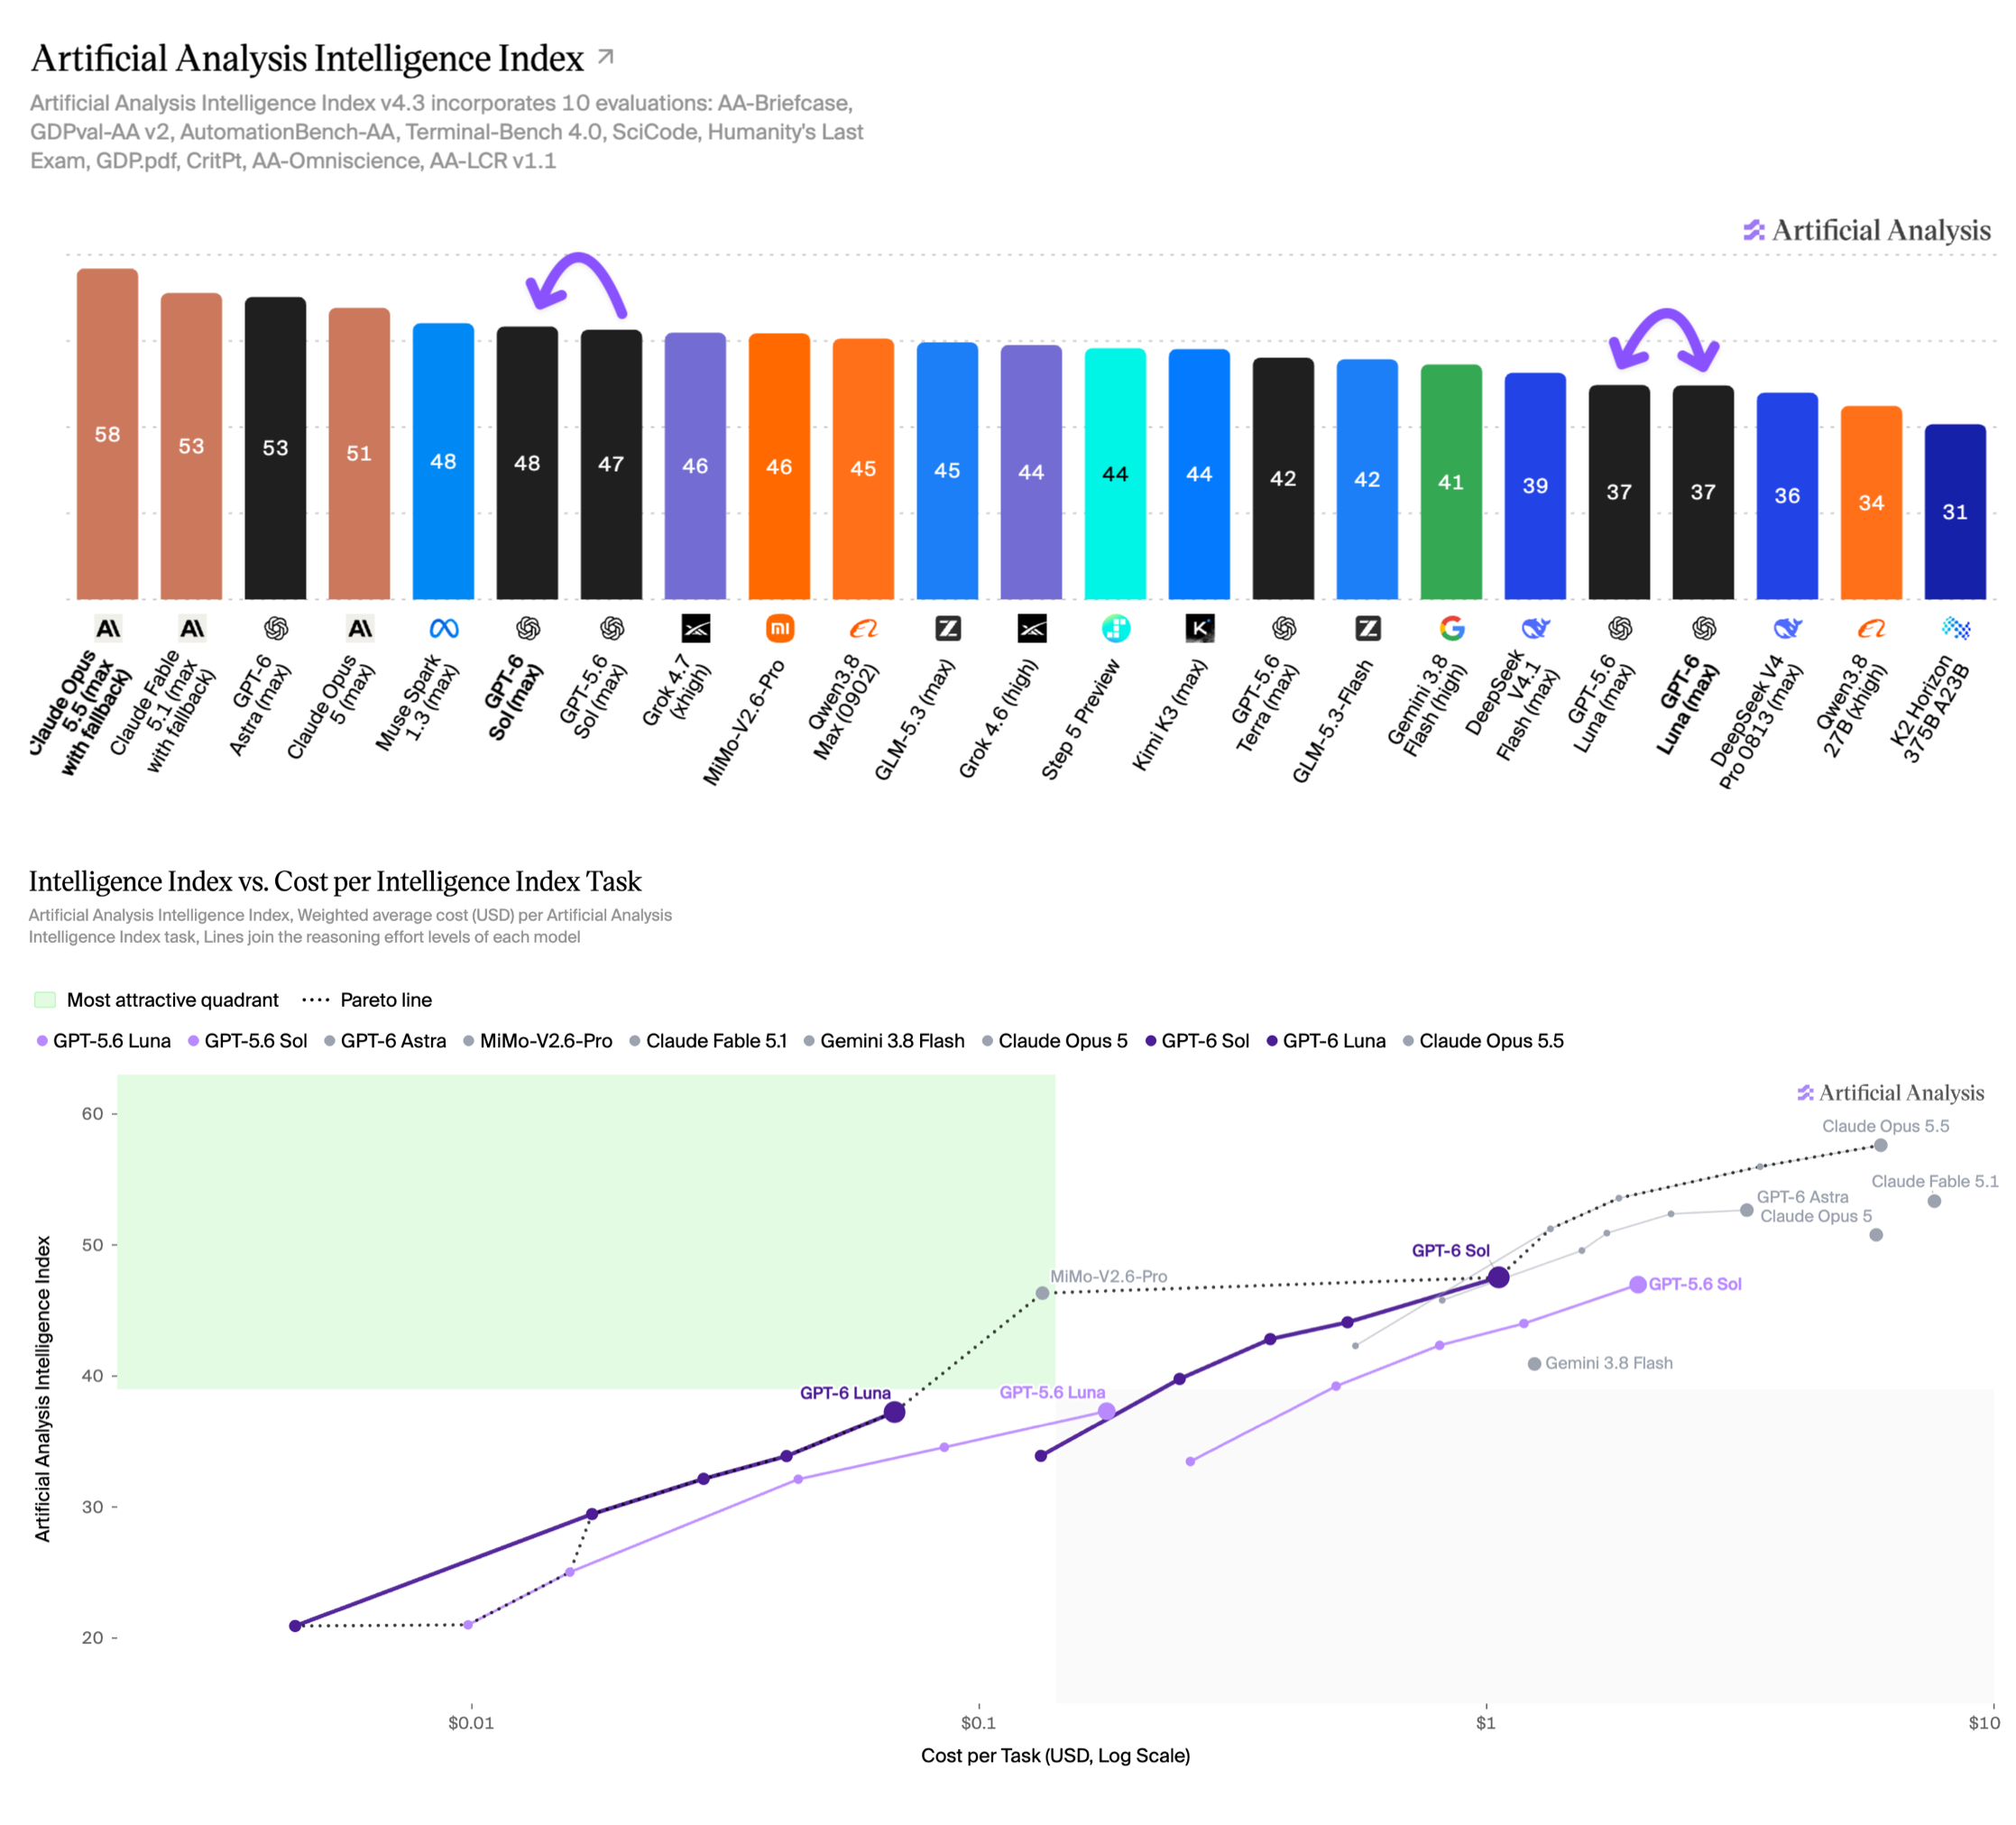
Figure. GPT-6 Sol (48) and Luna (37) on the same Index family, with cost/task — from GPT-6 Sol and Luna push the cost efficiency frontier (Sep 22, 2026).
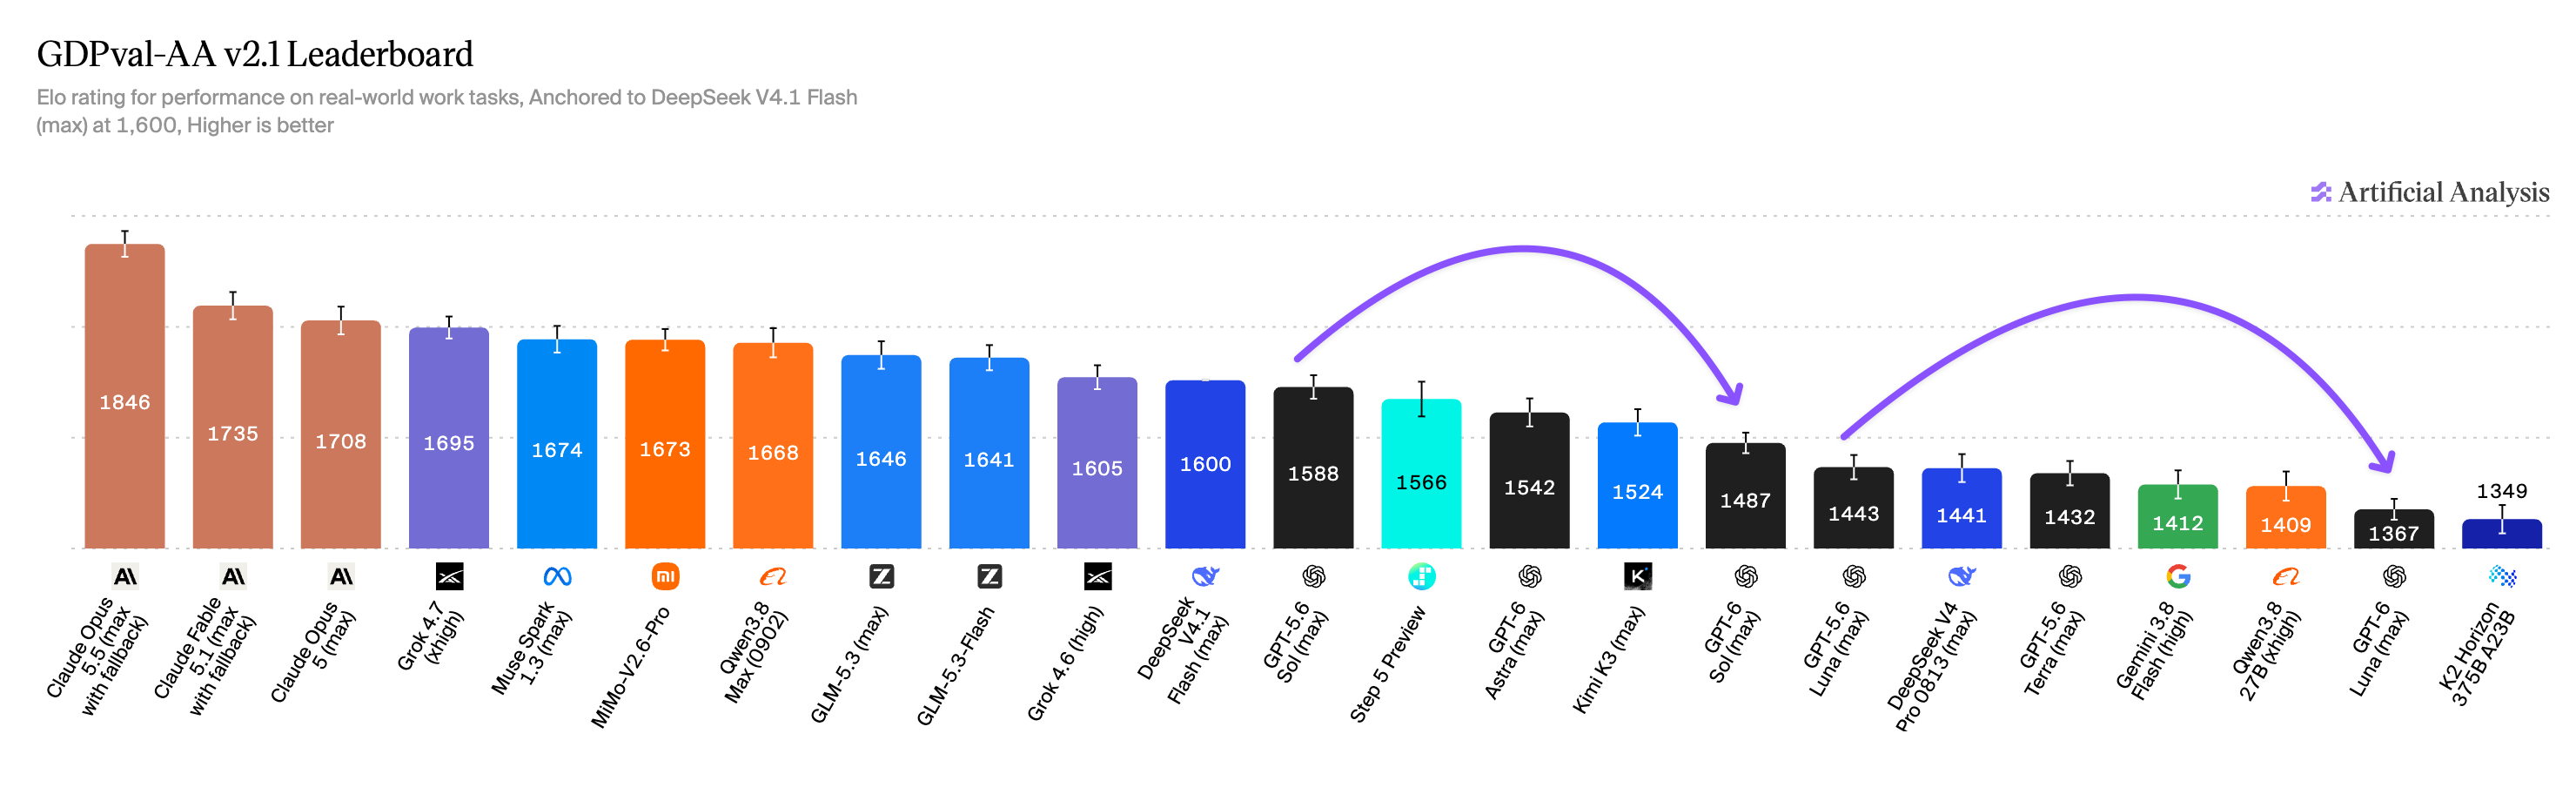
Figure. GDPval-AA v2.1 Elo leaderboard — from the same Sol/Luna AA article. AA flags knowledge-work regressions for Sol/Luna even as Index/cost looks friendly.
Harness note: Anthropic’s Opus post cites Terminal-Bench 4.0 at 66.4%. AA’s Opus Terminal-Bench is 59.6%. Different harness. Say so; do not reconcile them into one number.
LMArena: public text board still reads as a GPT-5.6 / prior-Opus era for these peers. No public Arena Elo for GPT-6 Sol, GPT-6 Luna, or Opus 5.5 confirmed for this pack. See LMArena text leaderboard. Omit Arena until a board cell exists.
Anthropic’s table (cite Anthropic)
Selected rows from Anthropic’s Opus 5.5 page. Peers in their table include GPT-6 Astra and GPT-5.6 Sol, not GPT-6 Sol. Label carefully.
| Bench (Anthropic report) | Opus 5.5 | GPT-6 Astra | GPT-5.6 Sol |
|---|---|---|---|
| Terminal-Bench 4.0 | 66.4% | 57.9% | 37.3% |
| FrontierCode v1.1 Main | 54.4% | 53.3% | 47.5% |
| CursorBench 4.0 | 57.8% | — | 41.7% |
| AutomationBench | 40.0% | 41.4% | 28.8% |
| GDPval-AA v2.1 Elo | 1846 | 1542 | 1588 |
Anthropic’s own caveat on that page: at this capability band, benchmark margins can understate real-world gaps; they frame efficiency vs Opus 5 as the clearer win (~40% less on typical workloads by their account; cache reads $0.20 vs $0.50). Footnotes on effort and Zapier AutomationBench (safeguard fallbacks as failures) are load-bearing.
Primary: https://www.anthropic.com/claude-opus-5-5
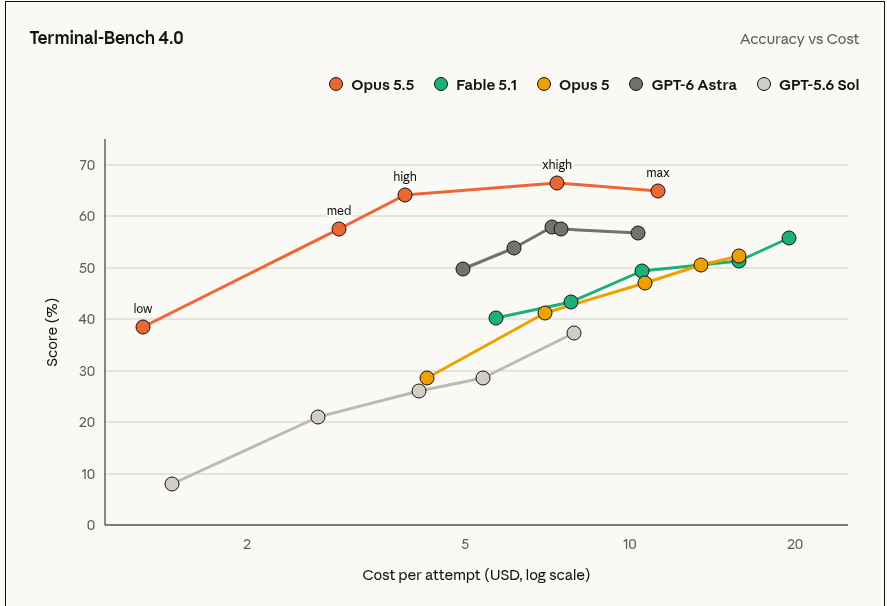
Figure. Terminal-Bench 4.0 accuracy vs cost (Anthropic harness / effort ladder) — screenshot from Claude Opus 5.5 (Sep 22, 2026). Peers include Astra and GPT-5.6 Sol, not GPT-6 Sol. Anthropic lists Opus at 66.4% here; AA’s Terminal-Bench for Opus is 59.6%.
OpenAI’s claims (cite OpenAI)
OpenAI’s Sol/Luna post sells the cost–intelligence curve under Astra. Sol is the professional / high-usage tier; Luna is the cheap tier. Token prices vs GPT-5.6 Sol promo: Sol half ($4→$2 input, $20→$10 output). Luna $0.10 / $0.50.
Selected OpenAI-reported points (effort labels and cost model are theirs):
- Sol xhigh AutomationBench 33.2% at $0.27/task vs Opus 5 max 26.9%
- DeepSWE: Sol max 68.8% (OpenAI frames near Fable 5 xhigh at much lower $/task)
- Other boards in that post (Agents’ Last Exam, FrontierCode, OSWorld) often compare to Opus 5 / Fable, not Opus 5.5
Desk rule: when both labs cite AutomationBench or FrontierCode, label whose harness, effort, and cost model. Do not merge OpenAI’s Opus 5 comparisons into Anthropic’s Opus 5.5 table.
Primary: https://openai.com/index/introducing-gpt-6-sol-and-luna/
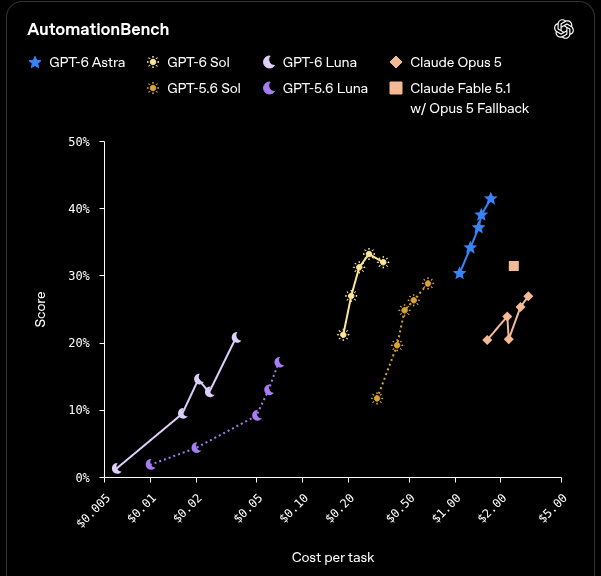
Figure. AutomationBench score vs cost per task — screenshot from Introducing GPT-6 Sol and Luna (Sep 22, 2026). OpenAI’s peers here are Opus 5 / Fable 5.1, not Opus 5.5. Do not mash this chart into Anthropic’s Opus 5.5 table.
One Gateway, two labs
If you already route agents through Vercel AI Gateway, same-day availability is the practical unlock: A/B without swapping vendor keys.
| Model | Gateway id | Token list (Gateway model pages) |
|---|---|---|
| Opus 5.5 | anthropic/claude-opus-5.5 (+ …-fast / speed option) | Anthropic list mirrored on Gateway |
| Sol | openai/gpt-6-sol | $2 / $10 |
| Luna | openai/gpt-6-luna | $0.10 / $0.50 |
Links:
- https://vercel.com/ai-gateway/models/claude-opus-5.5
- https://vercel.com/changelog/claude-opus-5-5-now-available-on-ai-gateway
- https://vercel.com/ai-gateway/models/gpt-6-sol
- https://vercel.com/ai-gateway/models/gpt-6-luna
- https://vercel.com/changelog/gpt-6-sol-and-luna-now-available-on-ai-gateway
Vercel’s Opus changelog also notes API behavior shifts worth a harness checklist: thinking is always adaptive (fixed budgets rejected); forced tool use is retired. That is process work, not a model beauty contest.
Operator takeaways
- 58 is a scoreboard cell, not a default. Re-run your harness before changing org defaults. Vendor boards are not your receipt. If you keep a typed next-edge / escalate ledger (see merge-graph), log per-step latency, $, and escalate rate on Sol vs Opus at medium effort first.
- Default to the cheaper tier that clears your quality bar. Reserve Astra / Fable-class spend — and Opus-everywhere — for the ambiguous tail, not every ticket because Index printed 58 on Tuesday.
- Treat effort as a product risk, not a free quality dial. Willison’s same-day note: Opus max can burn the 128k thinking ceiling on a silly pelican SVG (~$2.56 and no answer). Use max only when your loop can afford a miss. (Willison)
- Watch safeguard fallbacks and silent quality cliffs. Anthropic is explicit that cyber/bio routing can mute scores; production sees the same class of issue as “why did this run get dumber overnight?”
- One Gateway string change is cheaper than a key-rotation ceremony. That is the integration point of this week.
- LMArena still has no cells for these three models. Wait for a board stamp before treating Arena chatter as change-control.
What I’m not claiming
- That Opus 5.5 “beats” Sol (or vice versa) on every real workload
- That Anthropic’s Terminal-Bench 66.4% and AA’s 59.6% are the same measurement
- That AA Index 58 is a reason to flip org defaults without a harness re-run
- Any LMArena Elo for GPT-6 Sol, Luna, or Opus 5.5
- Any number not on the linked vendor, AA, or Vercel pages (or clearly attributed above)
- An IPO, listing, or S-1. Out of scope for this operator note.
Further reading / conversation
People whose same-window takes are complementary to the routing thesis (study-shelf; cite, don’t invent quotes):
- Claire Vo — task routing / heart vs week: GPT-6 Astra + Sol win enjoyment/clarity in her blind tests; Opus 5.5 wins work breadth / agentic week. Supports task-dependent defaults, not Index-as-fleet-policy. How I AI notes · Lenny
- Simon Willison — price table + max-effort ceiling: Sol/Luna halves; Opus max can burn the thinking budget and return nothing (~$2.56 ×2). Aligns with “effort is a product risk.” Weblog
- Addy Osmani — cost of a task / cost of a retry: token list ≠ task receipt; retries resend conversation and can erase list-price wins. Aligns with $/task over crown. Claude blog
- Peter Yang — harness vs model: prefers ChatGPT as harness and still calls Opus 5.5 the best model available right now (over Fable and Astra). Tension with this note’s default advice — cite carefully; the harness point travels, the crown does not. Indexed via Techmeme Sep 22
- Artificial Analysis — Index + cost/task primary independent scoreboard for this drop. Opus 5.5 · Sol/Luna cost frontier
- Vercel AI Gateway changelogs — same-day catalog for both labs. Opus · Sol/Luna
Sources (crawlable)
Vendors
Artificial Analysis
- https://artificialanalysis.ai/articles/claude-opus-5-5
- https://artificialanalysis.ai/models/claude-opus-5-5
- https://artificialanalysis.ai/articles/gpt-6-sol-and-luna-push-the-cost-efficiency-frontier
Vercel AI Gateway
- https://vercel.com/ai-gateway/models/claude-opus-5.5
- https://vercel.com/changelog/claude-opus-5-5-now-available-on-ai-gateway
- https://vercel.com/ai-gateway/models/gpt-6-sol
- https://vercel.com/ai-gateway/models/gpt-6-luna
- https://vercel.com/changelog/gpt-6-sol-and-luna-now-available-on-ai-gateway
LMArena (status only)
Study shelf (Further reading)
- https://simonwillison.net/2026/Sep/22/opus-and-sol-and-luna/
- https://claude.com/blog/what-a-task-costs-on-opus-5-5
- https://pod.wave.co/podcast/how-i-ai/opus-55-vs-gpt-6-sol-which-model-won-my-blind-taste-test
- https://www.lennysnewsletter.com/p/i-left-claude-for-months-opus-55
- https://www.techmeme.com/260922/p50
Related
- Pace the frontier — and the agents you already shipped — Contracts, HITL, evals, and spend/send/mutate gates for agents already in live ops.
- Lab · Merge Graph — Escalate ledger A/B: typed chooser stays on legal review steps — log per-step latency, $, escalate rate.